SIGGRAPH ASIA 2026

Asynchronous Multimodal
View Synthesis with
Probabilistic Temporal Encoding

1 University of North Carolina, Chapel Hill2 Stanford University

Abstract

We present D-FUSE, a feed-forward diffusion transformer that synthesizes novel views of dynamic scenes from asynchronous RGB and event cameras. Our probabilistic temporal encoding, ProbRoPE, represents each observation as a distribution over its capture interval, aligning sensors across viewpoints and sampling rates. Without strict synchronization or per-scene optimization, D-FUSE produces temporally consistent novel views under fast motion and sparse viewpoints.

Modern AI processes visual signals as tokens
Timeline
RGB · low FPS
Event · high FPS
1
2
3
4
4 frames
1
2
3
4
4 frames
1
2
3
4
4 frames
1
2
3
4
4 frames
1
2
3
4
4 frames
1
2
3
4
4 frames
Patchifier
4 frames ↓ 1 token
Token sequences
R1
R2
E1
E2
E3
E4
RGB tokens
Event tokens
t
02 / 08
Traditional temporal encoding processes time as a single point,
resulting in temporal aliasing
Token index
Index in the sequence
Does not reflect capture time
1
2
3
1
2
3
4
5
Physical timestamp
A timestamp on the timeline
Reflects capture time but not the interval
1.xx
5.xx
9.xx
1.xx
3.xx
5.xx
7.xx
9.xx
Low FPS input
GT
RoPE
03 / 08
Temporal encoding should encode a token as
an interval, not a point!
ProbRoPE
A distribution over time
Preserves both capture time and interval
Low FPS input
GT
ProbRoPE
04 / 08

RoPE

05 / 08

D-FUSE: synthesizing novel views from asynchronous multimodal videos

06 / 08

Synthetic Results

D-FUSE outperforms prior methods on synthetic multiview datasets.

Real World Results

D-FUSE synthesizes temporally consistent novel views from asynchronous real-world RGB and event streams.
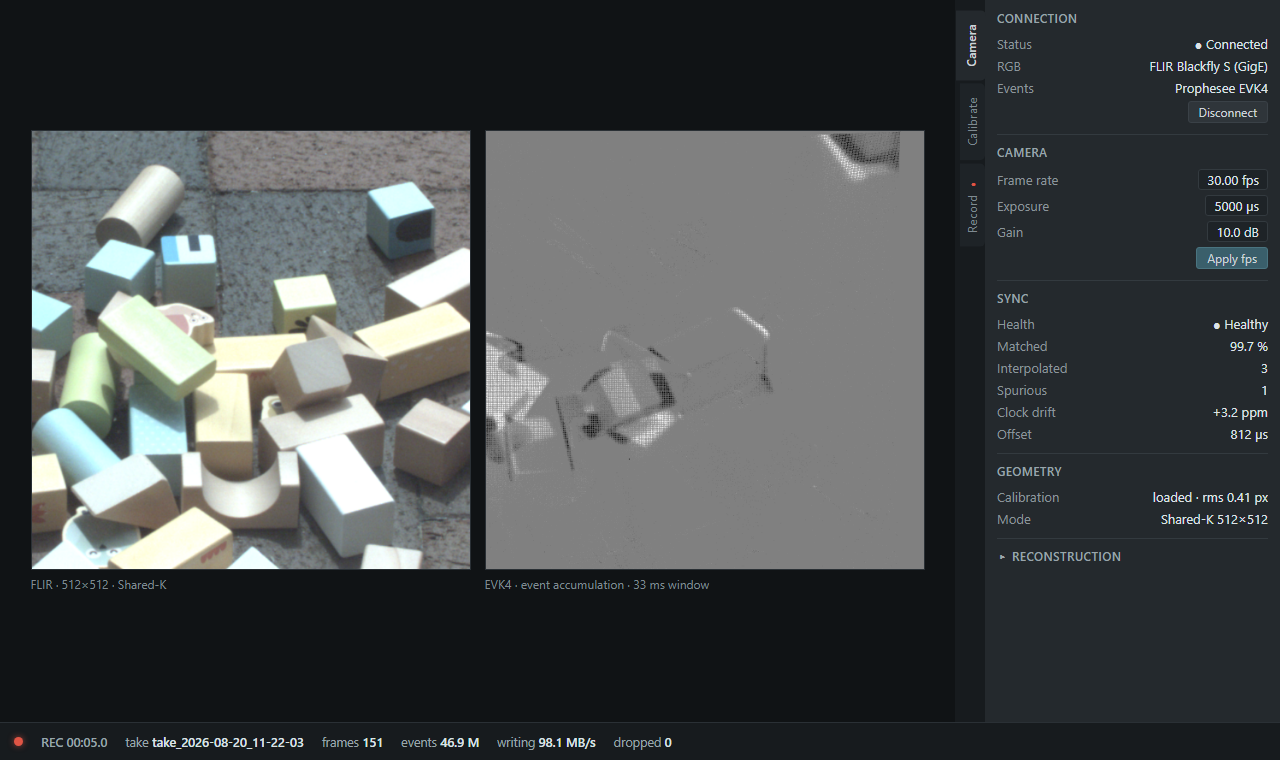
Fusion Studio interface with RGB and event camera previews, synchronization, and calibration controls.

Fusion Studio

Synchronizing multimodal cameras, calibrating their intrinsics and extrinsics, and capturing data can be painful when juggling different SDKs and software tools.

Try Fusion-Studio! Synchronization, calibration, and capture in one place!

View code

Cite this work

@inproceedings{zou2026asynchronous,
  title = {Asynchronous Multimodal View Synthesis with
           Probabilistic Temporal Encoding},
  author = {Zou, Zihao and Liu, Jiaming and Lian, Hengyu and
            Thadishetty, Nagasai and Chakravarthula, Praneeth},
  booktitle = {SIGGRAPH Asia 2026 Conference Papers},
  year = {2026},
  doi = {10.1145/3829340.3842258}
}